
ElevenLabs: AI Voice Generator
- Rating
- 4.7
- Downloads
- 5.00M
- Content Rating
- Everyone
ElevenLabs: AI Voice Generator - Screenshots
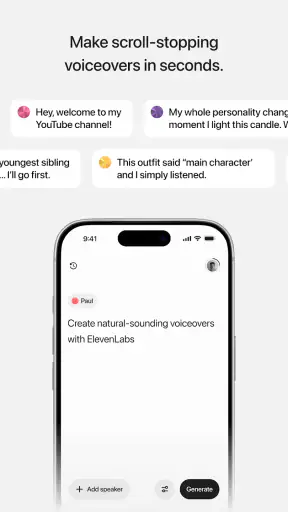
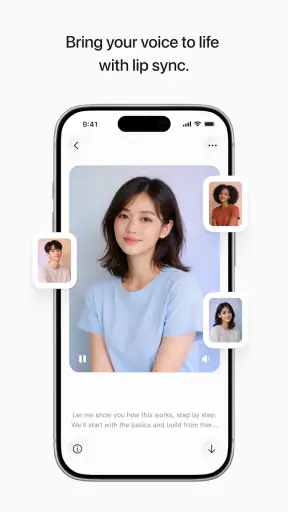
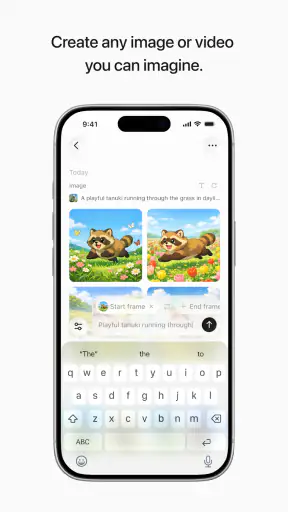
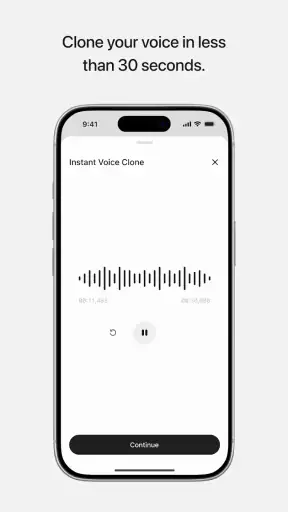
Pros
- Produces highly natural
- expressive voices in many languages.
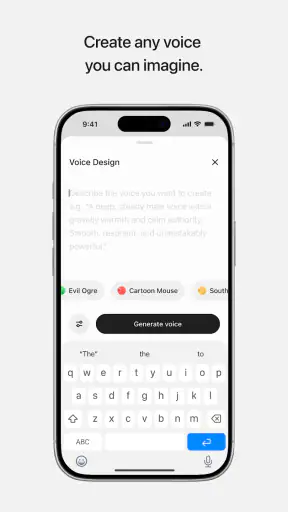
- Offers voice cloning for creating personalized narration styles.
- Useful for audiobooks
- videos
- podcasts
- and accessibility projects.
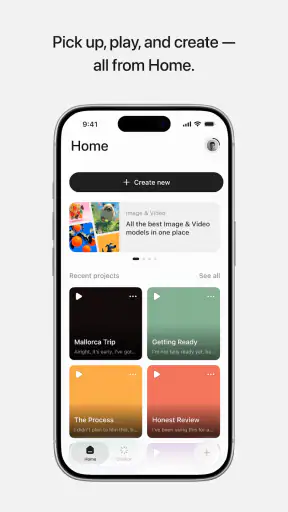
- Web and mobile access make projects easy to manage across devices.
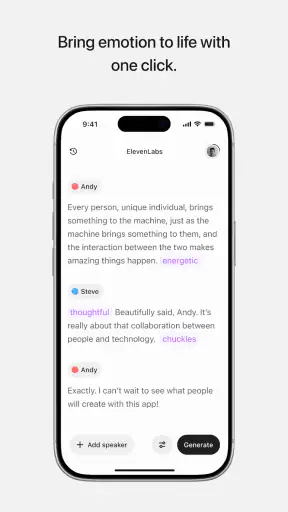
- Voice settings allow control over stability
- style
- and speaker similarity.
Cons
- Free usage includes limited credits and may run out quickly.
- Voice cloning requires suitable samples and can produce inconsistent results.
- Some advanced voices and features require a paid subscription.
- Generated speech may mispronounce unusual names or technical terms.
- Commercial usage rights depend on the selected plan and content type.
ElevenLabs: AI Voice Generator - Description
- App Name
- ElevenLabs: AI Voice Generator
- Package Name
- io.elevenlabs.coreapp
- Developer
- Eleven Labs Inc
- Category
- Music & Audio
- Last Updated
- Jun 24, 2025
- Version
- 0.0.101
I came away from ElevenLabs: AI Voice Generator with a fairly clear impression: it is a serious audio tool for people who need spoken content quickly, but it is not a complete replacement for a human narrator or a full recording studio. Its best quality is the way it turns written material into usable voice content without making the process feel like a technical project. That makes it especially appealing for creators who publish often and need to move from script to draft without setting up a microphone.
As a free Music & Audio app from Eleven Labs Inc, it sits in an interesting space between a simple text-to-speech utility and a creator-focused production tool. I would recommend trying it if you make videos, podcasts, narrated posts, lessons, or short-form social content. I would be more cautious if your work depends on very precise acting, highly personal delivery, or complete control over every breath and pause.
What using it feels like in everyday work
The most useful way to understand this app is to think of it as a bridge between writing and publishing. Instead of treating a script as the final product, I can use it to hear how the words actually sound. That distinction matters. A sentence that looks smooth on a screen may feel too long when spoken, while a paragraph that seems plain can become effective with the right rhythm.
For a short video, my practical workflow would be simple: write the narration, divide it into sensible sections, generate the voice, and listen while checking the script against the audio. I would then revise awkward wording rather than trying to repair every issue through voice settings. This is one of the app’s strongest lessons: good source writing still matters. Artificial speech can deliver a weak sentence clearly, but it cannot turn unclear thinking into a convincing story.
The app is particularly useful during the early stages of production. I can test several versions of an introduction, compare the pacing of two scripts, or create a temporary narration before spending time on visuals. That saves effort because I know whether the idea works aloud before editing a complete video around it.
It also helps with accessibility and convenience. Someone who prefers listening can turn written material into audio, while a creator can prepare narration without recording in a noisy room. For a small team, that can remove a bottleneck: the person writing the content does not necessarily need to be the person recording it.
The experience is not identical to having a performer in front of a microphone. Human narration carries tiny changes in emphasis, intention, and timing that are difficult to reproduce consistently. Still, for explanatory material, draft narration, announcements, and many social clips, the result can be practical enough to publish after careful listening.
Where the voice generation is most convincing
I find this kind of tool most convincing when the writing has a clear structure and the delivery does not need theatrical complexity. Tutorials, product explanations, travel notes, short news-style scripts, and calm educational passages are natural fits. The listener mainly needs clarity, steady pacing, and a voice that does not distract from the information.
The result becomes less dependable when the script relies on irony, subtle emotional shifts, comedy timing, or a character changing attitude halfway through a sentence. Those situations require interpretation rather than simple pronunciation. I would always review dramatic or sensitive material closely, because a technically clean reading can still feel emotionally wrong.
A useful technique is to write for the ear from the beginning. I keep sentences shorter, place important information near the start, and use punctuation to guide pauses. I also avoid stacking several parenthetical ideas into one line. This is not merely a writing preference; it gives the generated voice a better chance of sounding deliberate rather than rushed or mechanical.
Another practical tip is to split a long project into meaningful sections instead of treating the entire script as one block. Separate sections are easier to regenerate when one paragraph sounds awkward, and they make it simpler to align narration with scenes during editing. I would name those sections by purpose, such as opening, explanation, example, and closing, so revisions stay organized.
A realistic creator scenario
Imagine I run a small channel that publishes weekly explainers. I have the outline, but I cannot record because my home is noisy and I do not have time to repeat every line. I can use the app to produce a working narration, listen for sections that drag, and adjust the script before assembling the visuals. If the final piece is informal and information-led, that may be enough for publication. If the video depends on warmth or personal authority, I might use the generated version as a timing guide and record my own voice later.
That two-stage workflow is more valuable than simply pressing a button and accepting the first result. The generated audio becomes an editing reference: it reveals whether the introduction takes too long, whether an explanation needs an example, and whether the conclusion sounds abrupt. Even when I do not use the output as the final track, it can improve the content before recording.
For a language learner, the same approach can support listening practice with personal notes or short study scripts. For a freelancer, it can help create a rough voice sample for a client presentation. For a teacher, it can provide an audio version of prepared material. In each case, the benefit comes from reducing the distance between text and sound, not from eliminating human judgement.
The strongest reasons to choose it
The first strength is speed. A creator can move from an idea to an audible draft without arranging a recording session. That matters when the goal is to test several concepts quickly or keep a regular publishing schedule.
The second is flexibility in the writing stage. I can hear a script before committing to a final edit, which exposes problems that silent proofreading misses. This makes the app useful even for people who ultimately prefer their own voice.
The third is its focus. It is not trying to be a full digital audio workstation with a crowded timeline, mixing controls, and a long setup process. Its value is concentrated around spoken output. For someone who wants narration rather than a complete music-production environment, that narrower purpose can feel refreshingly direct.
The app also benefits from a low entry barrier. It is free to install, carries an Everyone age rating, and runs on Android versions starting with 7.0. That makes it accessible to a broad range of users and older devices. The current version is 0.0.101, so I would still keep expectations realistic about how quickly the experience may evolve as the product develops.
Its popularity gives me some confidence that it is not an obscure experiment. It holds a 4.7 average from around 205 thousand ratings, with more than 5 million installs. Those figures do not guarantee that every generated voice will suit my project, but they do suggest that the app has reached a substantial audience and earned strong overall approval.
The meaningful limitations I would consider first
The biggest limitation is not necessarily sound quality; it is control. When I need a performance to land on an exact emotional beat, small differences in emphasis can matter more than clean pronunciation. A generated voice may read the words correctly while missing the intention behind them. That is acceptable for many informational scripts, but it becomes a real issue for storytelling, acting, brand personality, or emotionally sensitive subjects.
There is also a review burden. Fast generation does not mean finished audio. I still need to listen for unusual pauses, names, abbreviations, numbers, and words with more than one common pronunciation. Proper nouns deserve special attention because a small pronunciation error can undermine an otherwise polished video.
Long-form work can create another kind of friction. Even when individual passages sound good, maintaining a natural sense of continuity across a lengthy project requires planning. I would keep a consistent script style, divide the material carefully, and check transitions between sections. Without that discipline, the final narration may feel assembled from separate pieces rather than delivered as one coherent performance.
The commercial model is worth considering before building a large workflow around it. The app is free, but in-app purchases range from $5.99 to $219.00 per item. I would begin with a small personal project, learn where the free experience ends, and only then decide whether paid use makes sense for my publishing schedule. A creator who produces occasional short clips may find the cost easier to justify than someone generating hours of narration every week.
I would also avoid treating it as a substitute for consent, editorial review, or responsible publishing. A convenient voice does not remove the need to check whether the script is accurate, whether the tone is appropriate, or whether the audience could be misled about who is speaking. The app can produce audio efficiently, but the creator remains responsible for the finished message.
How it compares with familiar alternatives
Compared with recording myself, the app is faster and more consistent in situations where my room, schedule, or microphone is the problem. My own voice is usually better for personal connection, spontaneity, and a recognizable identity. If viewers follow me because they want my personality, I would not replace that relationship entirely with generated narration.
Compared with basic text-to-speech already found in some phones and reading tools, this app feels more relevant to people who are making content rather than simply listening to text. A basic accessibility reader is excellent when the priority is convenience for private listening. A creator-oriented voice generator is more useful when the audio needs to become part of a video, presentation, or published piece.
Compared with hiring a voice actor, it is dramatically easier to iterate. I can rewrite a line and test it immediately instead of waiting for a new recording. A professional actor remains the better choice when interpretation, emotional range, character work, or a distinctive human identity is central to the project.
Compared with a conventional audio editor, the app removes much of the technical overhead but also does not replace detailed post-production. If I need careful noise repair, layered music, precise compression, or elaborate sound design, I would use a dedicated editor after generating the narration. The two tools can complement each other rather than compete directly.
Who will get the most value from it
I think it is a strong match for short-form creators, educators, marketers, independent publishers, and anyone who needs spoken drafts quickly. It is also useful for people who are uncomfortable recording themselves but still want to experiment with narrated content. The app can help turn a written idea into something testable without demanding a studio setup.
It is less suitable for a creator whose entire appeal depends on a personal voice, live energy, or intimate delivery. I would also hesitate to make it the only tool for audiobooks, dramatic fiction, character-led entertainment, or projects where every pause has expressive meaning. Those formats benefit from a human performance and more detailed production control.
Before committing, I would run a representative sample rather than a single flattering sentence. I would include a proper name, a number, a question, a long sentence, and the emotional tone used most often in my work. Then I would listen through headphones and phone speakers. That small test reveals much more than judging one isolated line.
It is also worth deciding whether the app belongs in the final production or only in the planning stage. Some users will publish the narration directly after editing. Others will use it to check pacing and then record themselves. Both workflows are valid, and recognizing that distinction prevents disappointment. The app is valuable even when it is not the final voice.
My final recommendation
After weighing the convenience against the creative limits, I see ElevenLabs: AI Voice Generator as a focused and useful tool rather than a magic shortcut. Its strongest contribution is helping me hear, revise, and produce spoken content quickly. For clear, structured narration, that can remove a major obstacle and make regular publishing more realistic.
I would start with the free version, test a complete short script, and listen critically before paying for anything. Keep the writing conversational, divide longer work into logical sections, and treat names, punctuation, and emotional passages as areas requiring extra review. Those habits make a bigger difference than simply generating more audio.
My recommendation is positive for creators who value speed and iteration, especially when a polished draft matters more than a deeply personal performance. I would skip it as a primary solution if the project depends on unmistakable human character or fine-grained acting. In the right role, though, it is a capable companion between the blank page and a finished piece of audio.
FAQ
What is ElevenLabs: AI Voice Generator used for?
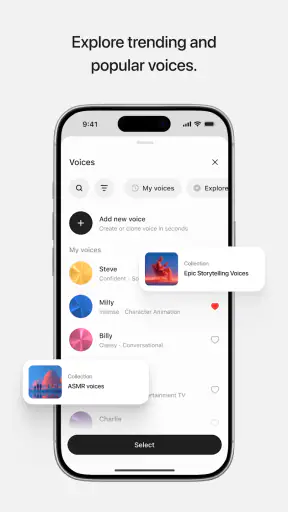
ElevenLabs is an AI-powered voice generation app designed to turn written text into natural-sounding speech. It can be useful for narration, videos, podcasts, presentations, audiobooks, accessibility, and creative projects. After testing its workflow, the main appeal is the realistic delivery and variety of available voices, although the quality and available tools can depend on your selected plan and supported language.
Does ElevenLabs support multiple languages and different voice styles?
Yes, ElevenLabs supports voice generation in multiple languages, and the available voices can offer different tones, accents, and delivery styles. Results may vary depending on the language, text, punctuation, and voice selected. English generally provides a broad selection of options, while some less commonly supported languages may have fewer voices or less consistent pronunciation.
Can I create or clone a custom voice with ElevenLabs?
ElevenLabs may provide voice design or voice-cloning features, depending on the current app version, account type, and regional availability. These tools should be used responsibly and only with appropriate permission from the voice owner. Before creating a clone, users should review the platform’s consent requirements, usage rules, and commercial restrictions, since unauthorized imitation of another person’s voice can create serious ethical and legal problems.
Is ElevenLabs free to use, or does it require a subscription?
ElevenLabs generally offers limited access through a free tier or trial, but usage is controlled by character, credit, or generation limits. Regular users who need longer narration, more monthly output, premium voices, commercial rights, or advanced features may need to choose a paid subscription. Pricing, limits, and included tools can change, so checking the current plan details before downloading or subscribing is recommended.
Is the audio created with ElevenLabs suitable for commercial projects?
Audio generated with ElevenLabs may be usable in commercial projects, but this depends on your subscription plan, the specific feature used, and the platform’s current licensing terms. Free or trial access may include restrictions on monetization, attribution, or redistribution. If you plan to publish advertisements, videos, courses, podcasts, or client work, carefully review the applicable terms and confirm that your chosen voice and content are permitted.


